SXF SECURITY REFERENCE / PROMPT INJECTION
Prompt Injection in AI in 2026:
Direct vs Indirect Attacks, Risks & Defenses
Prompt injection is one of the defining security problems of modern AI systems because models process instructions and data through the same natural-language interface. The risk grows sharply when AI can browse, retrieve documents, use tools, call MCP servers or act as an agent. This guide explains the threat model, the difference between direct and indirect injection, why simple filters are not enough, and how to design systems that remain bounded even when a model is manipulated.
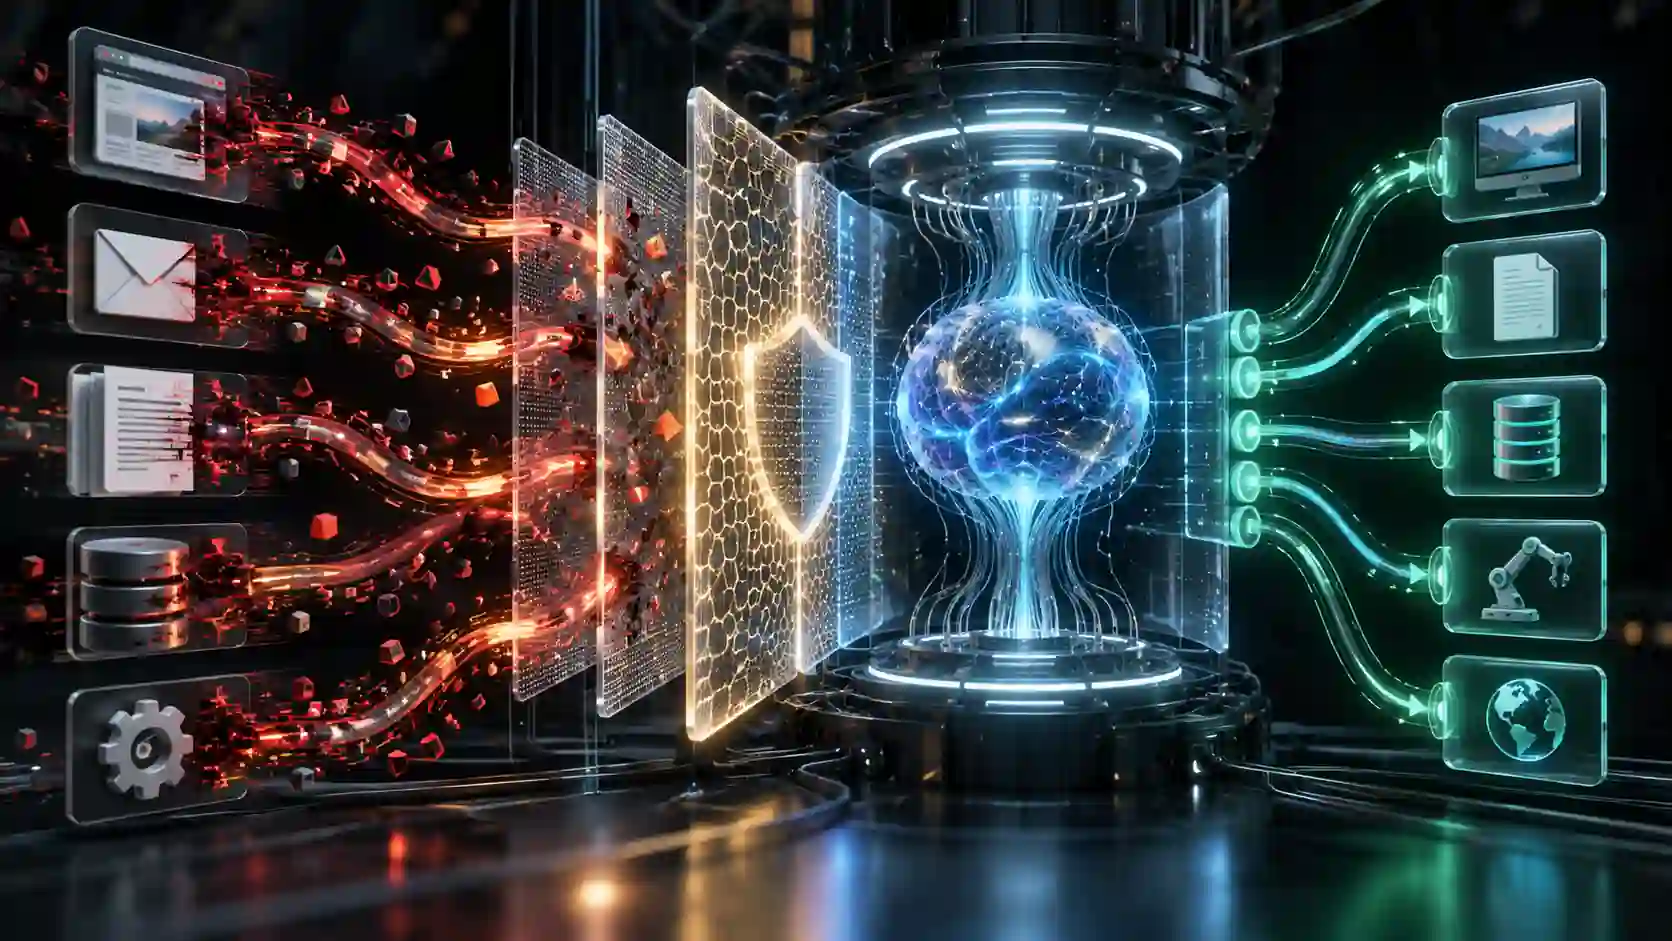
Prompt injection happens when untrusted input is interpreted as instruction — and the safest design assumes some injections will get through.
Direct prompt injection comes from the user or attacker interacting with the model directly. Indirect prompt injection is embedded in external content the model reads, such as webpages, email, documents, RAG results or tool output. For agents, the impact can extend beyond a bad answer because the model may also have access to private data and actions. Effective defense therefore combines model-level resistance with deterministic controls: trust separation, least privilege, constrained tools, isolated execution, data boundaries, contextual human approval, monitoring and rapid revocation.
DEFINITION
What is prompt injection in AI?
Prompt injection is a security failure in which untrusted input changes an AI system's behavior in ways the user or application did not intend. NIST defines prompt injection as an attack that exploits the concatenation of untrusted input with a prompt constructed by a higher-trust party, such as an application designer.
That definition is useful because it describes the core architectural problem: natural-language AI systems often process instructions and data through the same model context. A sentence retrieved from a trusted policy file and a sentence retrieved from an untrusted webpage may both arrive as tokens the model can reason over. Unless the surrounding system preserves trust boundaries, external content can influence behavior that should have been controlled by higher-trust instructions.
OWASP lists Prompt Injection as LLM01 in its current GenAI security guidance and notes that RAG and fine-tuning do not fully remove the vulnerability. OpenAI describes prompt injection as an evolving form of social engineering against AI systems: the model is being persuaded or misled using content placed in its context.
See how permissions, MCP, sandboxing, memory and approvals change the blast radius.
CORE DISTINCTION
Direct vs indirect prompt injection: what is the difference?
The most important distinction is where the untrusted instruction enters the model context.
The user input itself attempts to override, redirect or confuse higher-priority instructions. The application knows where the input came from, even if it cannot reliably determine what the user intends.
The model encounters attacker-controlled instructions while reading a webpage, email, file, repository, search result, database record or tool response. The end user may never see the malicious content.
Indirect injection is especially important for agents because the system may retrieve content automatically. A user can ask an agent to perform an ordinary task while the attacker controls only one of the sources that the agent later reads. NIST often refers to this pattern as agent hijacking when the external instruction redirects an agent toward unintended actions.
The attacker does not need to control the user's prompt if they can control something the model will later ingest. That is why web browsing, email, RAG and tool output all belong in the prompt-injection threat model.
TERMINOLOGY
Prompt injection vs jailbreak: related, but not the same problem
The terms are often mixed together, but the distinction matters for engineering. Prompt injection is the broader class of attacks that use input to alter model behavior in an unintended way. Jailbreaking usually refers to attempts to bypass model-level safety restrictions or content policies directly.
The application or agent's intended behavior, instruction hierarchy, data boundaries and tool decisions.
The model's built-in safety or refusal behavior.
User input or external content such as webpages, files, email, RAG context and tool responses.
Direct interaction designed to persuade the model to ignore or reinterpret restrictions.
Can become an authorization or data-security issue when the model controls tools or private context.
Often manifests as unsafe or disallowed output, though agents can increase the impact.
OWASP explicitly notes the overlap. In practice, security teams should avoid arguing over labels and instead model the trust boundary: what untrusted content can reach the model, and what authority can the resulting model output influence?
AGENTIC RISK
Why prompt injection is more dangerous for AI agents
A chatbot can be manipulated into producing a bad answer. An agent can be manipulated into choosing an action. That changes the impact profile.
OpenAI's 2026 security guidance argues that modern attacks increasingly resemble social engineering rather than simple phrases that can be blocked by a filter. Microsoft similarly emphasizes that once AI tools move from reading to acting, prompt injection can cross from content manipulation into real operational impact.
Private data
The agent may read email, documents, repositories, customer records or other sensitive context.
Tools
The agent may call APIs, search internal systems, send messages or modify external state.
Execution
Coding and computer-use agents may run commands, modify files or operate browsers.
Persistence
Memory or long-running workflows can carry the effects of compromised context beyond one turn.
NIST's 2026 agent-security red-teaming work describes indirect prompt injection as a central risk for agents that process emails, websites and code repositories. The useful framing is simple: prompt injection becomes more consequential as the distance between model output and real-world authority shrinks.
ATTACK SURFACE
Where prompt injection enters an AI system
Prompt injection is not tied to one interface. Any content that reaches the model and can be influenced by a lower-trust party can become part of the attack surface.
Web pages
Browser agents and research systems ingest text, metadata and page structure from content they do not control.
Email & messages
Assistants that summarize or act on inbox content may process instructions sent by external parties.
Documents & files
PDFs, office documents, tickets, resumes, issue descriptions and attachments can introduce untrusted instructions.
Retrieved knowledge
Search indexes, vector stores and knowledge bases can surface content with different trust levels into one context window.
Tool output
Agents may treat API or MCP responses as factual context even when the upstream service is compromised or simply untrusted.
Memory & summaries
Untrusted content can become more dangerous if it is persisted and later treated as durable context.
This is why a defensive architecture should track provenance. The model should not receive a flat undifferentiated block of text when the application knows which parts came from system policy, the user, an internal database or the public web.
RAG SECURITY
RAG prompt injection: why retrieval does not make untrusted content safe
Retrieval-augmented generation improves relevance by bringing external information into the model context. It does not automatically establish the trustworthiness of that information. OWASP explicitly notes that RAG does not fully mitigate prompt injection.
A secure RAG design separates relevance from authority. A retrieved document can be highly relevant to the user's question and still be untrusted for instruction-following. Search ranking, similarity score or database location should not automatically make retrieved text equivalent to system policy.
The application should know whether context came from policy, internal documentation, a customer upload or an external source.
Smaller, task-specific context reduces unnecessary exposure and makes policy reasoning easier.
If the task needs a date, status or identifier, structured extraction can be safer than passing a full free-form document into an agent planner.
The fact that a document mentions an action should never grant the agent authority to perform it.
REAL-WORLD INPUTS
Browser, email and document prompt injection
Anthropic's browser-security work highlights a core problem: every webpage an agent visits is potentially adversarial. The same logic applies to email and uploaded documents. A system designed to “read what the user would read” is now also reading content authored by people who may want to influence the agent rather than inform the user.
For browser agents, the safest architecture minimizes the number of sensitive resources reachable in the same workflow. If a task only requires public research, the agent should not simultaneously have broad access to private enterprise data and write-capable tools. For email, distinguish reading, drafting and sending. For documents, separate extraction and summarization from privileged action.
When possible, separate “collect untrusted information” from “act on trusted data.” The fewer sensitive sinks available while the agent is processing adversarial sources, the lower the blast radius of an injection.
TOOLS & MCP
Prompt injection, MCP and tool use: where model influence becomes system authority
Tools make prompt injection materially more serious because a model output can become an API call. MCP expands this surface by standardizing how agents discover and use tools, resources and prompts from external servers.
The security rule is not “MCP is dangerous.” It is that every tool connection creates a trust boundary. Tool descriptions, arguments, results and credentials can all influence the agent loop. A compromised or poorly governed integration can therefore amplify a prompt-injection failure.
Do not expose every connected tool to every agent or task.
Descriptions enter model context and can influence which actions the model considers appropriate.
Use schemas and policy checks before turning model-generated parameters into an external action.
The downstream service should enforce identity, resource scope and operation permissions independently.
Responses can contain content that attempts to steer the next model decision.
See MCP security, identity, sandboxing, memory and approvals in the full agent-security reference.
MULTIMODAL AI
Multimodal prompt injection: instructions do not have to arrive as ordinary visible text
OWASP notes that multimodal systems expand the attack surface because models can process combinations of text, images and other content. The important defensive lesson is not a specific hiding technique; it is that human-visible content and model-parsed content are not always the same thing.
Applications should therefore treat files and media as untrusted inputs even when a human reviewer sees nothing suspicious at a glance. The same provenance and permission rules should apply regardless of modality: a model interpretation of an image, document or webpage does not inherit authority simply because the content looks benign.
IMPACT
What can prompt injection cause?
The outcome depends on the system surrounding the model. In a low-authority chatbot, injection may distort output. In a tool-using agent, the same class of manipulation can have much broader consequences.
The model can produce misleading, biased or attacker-influenced summaries and recommendations.
A manipulated workflow may reveal information the user did not intend to share with the current destination.
The model can attempt an action that is outside the user's real task but inside the tool's available capability.
Injected context can influence ranking, triage, approval or other model-assisted decisions.
If an agent can run code or commands, model influence can cross into an execution boundary unless the environment is isolated and policy-controlled.
Low-trust content can affect later tasks if it is stored in memory or reused summaries without appropriate validation.
Microsoft's 2026 research into agent frameworks illustrates why the surrounding architecture matters: when natural-language decisions connect directly to privileged plugins or code execution, injection can become a route to much more serious system impact. The defensive response is to constrain that transition rather than assume the model will always recognize the attack.
DEFENSE IN DEPTH
How to defend against prompt injection in AI systems
There is no single filter, prompt template or model setting that should be treated as complete protection. OpenAI, Anthropic, OWASP, NIST and Microsoft all point toward layered defenses: improve model resistance, but design the application so a successful manipulation cannot automatically become a high-impact action.
Increase resistance
Use models and training techniques designed to distinguish user intent from adversarial content and to treat suspicious instructions cautiously.
Preserve trust boundaries
Label provenance, separate system policy from untrusted content and avoid flattening every source into one undifferentiated prompt.
Limit permissions
Give the agent only the data and actions needed for the current task, for the shortest practical duration.
Constrain tools
Validate parameters, use allowlists, sandbox execution and restrict network destinations and resource access.
Approve, observe, revoke
Require confirmation at consequential boundaries, log the action chain and keep a fast way to disable the agent.
Why input filtering is not enough
OpenAI's 2026 guidance describes prompt injection as increasingly similar to social engineering. That is important because social engineering is contextual. An attacker does not need a fixed phrase that a regex or classifier can catch every time. The content can look like a plausible request, warning, instruction or business process.
Detection remains useful, but it should reduce probability rather than define the only security boundary. The system should remain bounded when detection fails.
BLAST RADIUS
Least privilege is the strongest practical defense against prompt-injection impact
Prompt injection is a model-influence problem. Least privilege turns it into a bounded system problem. If the agent cannot read a secret, send an external message or modify production state, an injection cannot use those capabilities either.
Analysis and research tasks should not automatically inherit write permissions.
LOWER RISKExpose only the records, files or repositories necessary for the current request.
MINIMIZE DATALimit the set of operations available to the agent instead of exposing an entire application API.
BOUND TOOLSUse temporary credentials or delegated permissions that expire when the task ends.
LIMIT TIMEAn agent should not be able to grant itself broader permissions because external content suggested it.
CRITICALNIST's work on agent identity and authorization reinforces the same direction: agents need explicit identity, authorization, auditing and controls designed for their operating context.
TRUST & PROVENANCE
Separate trusted instructions from untrusted content
One of the most useful design improvements is to keep source identity visible throughout the system. The application often knows more about trust than the model does. It knows which text came from the developer, the authenticated user, an internal policy database, the public web or a third-party tool.
These define what the application allows. They should not be editable through retrieved content.
The user's request matters, but it is still bounded by permissions, organizational policy and safety controls.
Useful for reasoning, but not automatically authoritative for changing system behavior.
These may contain relevant facts and hostile instructions at the same time.
Structured interfaces can help. If an agent only needs a few fields from a source, extracting those fields can reduce the amount of natural-language content that enters the planning context. This is not a complete defense, but it can simplify the trust model.
HUMAN CONTROL
Human approval: where it helps and where it fails
Human approval is one of the most important controls for consequential agent actions, but it is not magic. A manipulated model can also manipulate the explanation shown to the user. Approval design therefore needs to expose the actual action, not only the model's natural-language summary of that action.
| Action type | Recommended default | Approval design |
|---|---|---|
| Read public information | Automatic | Keep access scoped; no need to interrupt the user for ordinary reads. |
| Read private data | Policy-controlled | Authorize by user, tenant and task rather than relying on model intent. |
| Create draft or proposed change | Automatic in bounded workspace | Keep output reviewable before it creates an external side effect. |
| Send, publish or share | Contextual confirmation | Show exact destination, content and identity being used. |
| Delete, deploy, pay or change access | Strong confirmation + policy | Show target and consequences; require fresh authority for high-impact actions. |
Approval fatigue is a real security problem. Ask for confirmation at meaningful boundaries rather than every trivial step. The goal is to preserve human control where the consequence changes, not to create an endless stream of prompts users learn to dismiss.
ASSURANCE
Prompt-injection monitoring, evaluation and red teaming
Defenses should be tested against the actual workflow. A model may look robust in a chat-only benchmark and still fail when connected to a browser, a document retriever and write-capable tools.
Test direct and indirect sources
Evaluate how the system handles untrusted user input, web content, documents, messages and tool output.
Test the action boundary
Measure whether manipulated context can change tool choice, authorization requests or external side effects.
Record provenance
Preserve enough source information to understand which content influenced a decision.
Trace tools and approvals
Record proposed action, policy result, human decision, target and resulting side effect.
Detect behavior drift
Watch for unusual tools, destinations, repeated denials or action sequences that do not fit the task.
Contain quickly
Revoke tokens, disable connectors, stop active sessions and remove poisoned persistent context when needed.
NIST's large-scale agent red-teaming research is useful here because it treats agent hijacking as a measurable system property, not merely a prompt-quality issue. The relevant metric is not only whether the model recognized the attack; it is whether the complete agent remained within the intended task and authority.
ENTERPRISE DESIGN
A reference architecture for prompt-injection-resistant AI applications
For enterprise systems, the safest pattern is to interpose policy and trust boundaries between the model and every sensitive capability. A practical high-level flow looks like this:
User intent
Authenticate the user and capture the requested task with relevant organizational policy.
Context broker
Retrieve data with source labels, trust level and minimum necessary scope.
Agent/model
Reason over the task while keeping external content distinguishable from application policy.
Policy gateway
Evaluate proposed tools and actions deterministically against identity, target and operation.
Tool sandbox
Execute bounded operations with restricted filesystem, network and credentials where appropriate.
Human approval
Escalate only actions whose external consequence requires explicit user authority.
External system
Re-authorize at the downstream service rather than trusting the model or orchestrator alone.
Audit & response
Log decisions and outcomes, detect anomalies and maintain a tested revocation path.
Microsoft's current enterprise tooling also reflects this layered approach. Its prompt-injection protection scans model traffic, but Microsoft separately emphasizes identity, tool governance and agent security because detection by itself is not sufficient.
This guide is the durable reference; the topic layer tracks vendor, framework and standards changes.
PRODUCTION CHECKLIST
Prompt injection defense checklist
FAQ
Frequently asked questions about prompt injection
What is prompt injection in AI?
Prompt injection is an attack or failure mode in which untrusted input changes an AI system's behavior in ways the user or application did not intend. It becomes a security issue when the manipulated model can access sensitive data, tools or consequential actions.
What is indirect prompt injection?
Indirect prompt injection occurs when an AI system encounters instructions embedded in external content such as a webpage, email, document, RAG result, repository or tool output. The user may never see the malicious or misleading instruction directly.
What is the difference between direct and indirect prompt injection?
Direct injection is delivered through the user's interaction with the model. Indirect injection arrives through content the model retrieves or processes while doing another task.
What is the difference between prompt injection and jailbreaking?
Prompt injection is the broader problem of manipulating model behavior through input. Jailbreaking usually refers to directly bypassing a model's built-in safety restrictions. The concepts overlap, but prompt injection is especially important at the application and agent layer.
Can prompt injection be completely prevented?
No current technique should be treated as complete prevention. Strong systems combine model resistance with deterministic controls around permissions, tools, data, execution, approvals and monitoring so that successful manipulation has limited impact.
Does RAG prevent prompt injection?
No. Retrieval can improve relevance, but retrieved content may still be untrusted or attacker-controlled. RAG systems need provenance, trust separation, minimum necessary retrieval and independent authorization for actions.
Why is prompt injection dangerous for AI agents?
Agents can browse, use tools, access private data and create external side effects. A manipulated model can therefore turn an input problem into an authorization, data exposure or operational problem.
How do you defend against indirect prompt injection?
Use defense in depth: treat external content as untrusted, preserve provenance, limit permissions, constrain tools, isolate execution, protect secrets, require contextual approval for consequential actions and monitor the full action chain.
Is input filtering enough to stop prompt injection?
No. Filtering can reduce exposure, but modern attacks can be contextual and resemble social engineering. The surrounding system should remain bounded even when detection fails.
How should companies test for prompt injection?
Test the complete production workflow with representative untrusted sources, tool boundaries and permission levels. Measure whether the agent stays within the intended task and authority, not only whether the model labels an input as malicious.
PRIMARY SOURCES
Official sources used for this guide
This reference prioritizes standards organizations, security research and first-party product guidance. Vendor material is used to describe threat models and implemented defenses; no vendor's claims are treated as proof that prompt injection is solved.