SXF GUIDE / AGENTIC SYSTEMS
How to Build an AI Super Agent:
Architecture, Memory, Tools & Multi-Agent Orchestration
A useful super agent is not a swarm of models with a dramatic name. It is a deliberately engineered system that knows what job it owns, when to delegate, which tools each specialist may use, how to preserve state, how to verify the work and when a human must approve the next action. This guide builds that system from first principles and connects the architecture to current OpenAI, Anthropic, MCP and agent-security practice.
Build the smallest agent system that can reliably own the outcome—then add orchestration, specialists and autonomy only where they earn their complexity.
A production AI super agent normally needs five layers: a clear orchestrator, bounded specialist agents, a controlled tool and integration layer, intentional state and memory, and a verification/governance layer. The orchestrator decides whether to solve a step directly, call a specialist, use a tool, ask for approval or stop. Specialists should be narrow. Tools should follow least privilege. Memory should be structured outside the model where possible. And important work should be verified before the system declares success.
SYSTEM DEFINITION
What are we actually building?
An AI super agent is best treated as a system architecture, not as a special kind of foundation model. The system accepts an outcome-level goal, chooses how the work should be decomposed, routes tasks to models, agents or deterministic tools, keeps track of the state of the job, checks results and returns one coherent outcome. In other words, the “super” part is usually the control plane.
That distinction matters because the term is still not a formal standard. Your architecture should therefore be grounded in observable capabilities instead of marketing labels. OpenAI's current agent documentation describes an agent as a package of a model, instructions and optional runtime behavior such as tools, guardrails, MCP servers, handoffs and structured outputs. A super-agent design composes those primitives into a larger governed workflow.
If the system only sends one prompt and returns one answer, you are not building a super agent. If it can interpret a goal, choose capabilities, observe execution, change strategy and decide when the job is actually complete, you are building an agentic control system.
This article focuses on that control system. For the terminology, product landscape and difference from AGI, see the existing AI Super Agents in 2026 reference guide.
COMPLEXITY BUDGET
First question: should this be a super agent at all?
The fastest way to build an unreliable agent is to add autonomy before proving that the task needs it. A deterministic workflow is easier to test. A single model call is cheaper to understand. A single agent with two good tools is easier to secure than six agents that can all call everything.
Start by classifying the work. If the sequence is known in advance, keep it deterministic. If the input varies but the correct path can be classified, use routing. If several independent perspectives or searches are useful, use parallelization. Use an orchestrator-worker design when the system has to decide at runtime which subtasks exist and how they should be assigned.
Summarization, extraction, rewriting, classification or generation with a clear input/output contract.
Fixed approvals, ETL-like sequences, repeatable content pipelines and business rules.
The model needs to choose tools and recover from normal failures, but one control loop is enough.
Open-ended tasks, multiple specialist domains, parallel exploration, separate permissions or long-running work.
Anthropic's published multi-agent research system is a useful real-world example of the last category: a lead agent decomposes broad research tasks and creates parallel subagents to explore independent directions. Anthropic reported a 90.2% improvement over a single-agent baseline on one internal breadth-heavy research evaluation; that is an internal result, not a universal benchmark, but it illustrates the kind of task where multi-agent coordination can pay.
STEP 01 / DEFINE THE JOB
Write the outcome before you write the agents.
“Build a research super agent” is not a requirement. “Given a company and market, gather current primary sources, extract comparable facts, identify uncertainty, produce a sourced briefing and stop when every required field has evidence” is a requirement. The second version gives the system something it can actually complete and gives you something you can evaluate.
Define five things before implementation
What does done look like?
Specify the artifact or real-world state the system must produce—not merely “help the user.”
What must be true?
Define required sources, fields, checks, tolerances or external confirmations.
What may it change?
Separate read access, reversible actions and high-impact actions that require approval.
When should it stop?
Set time, cost, retry, uncertainty and escalation limits before the first production run.
Also write down who owns failure. If an agent cannot obtain a source, should it continue with a caveat, use a secondary source, ask the user or stop? If a tool returns contradictory data, who adjudicates? These decisions belong in the product specification, not inside an improvised prompt.
STEP 02 / ARCHITECTURE
A practical reference architecture for a super agent
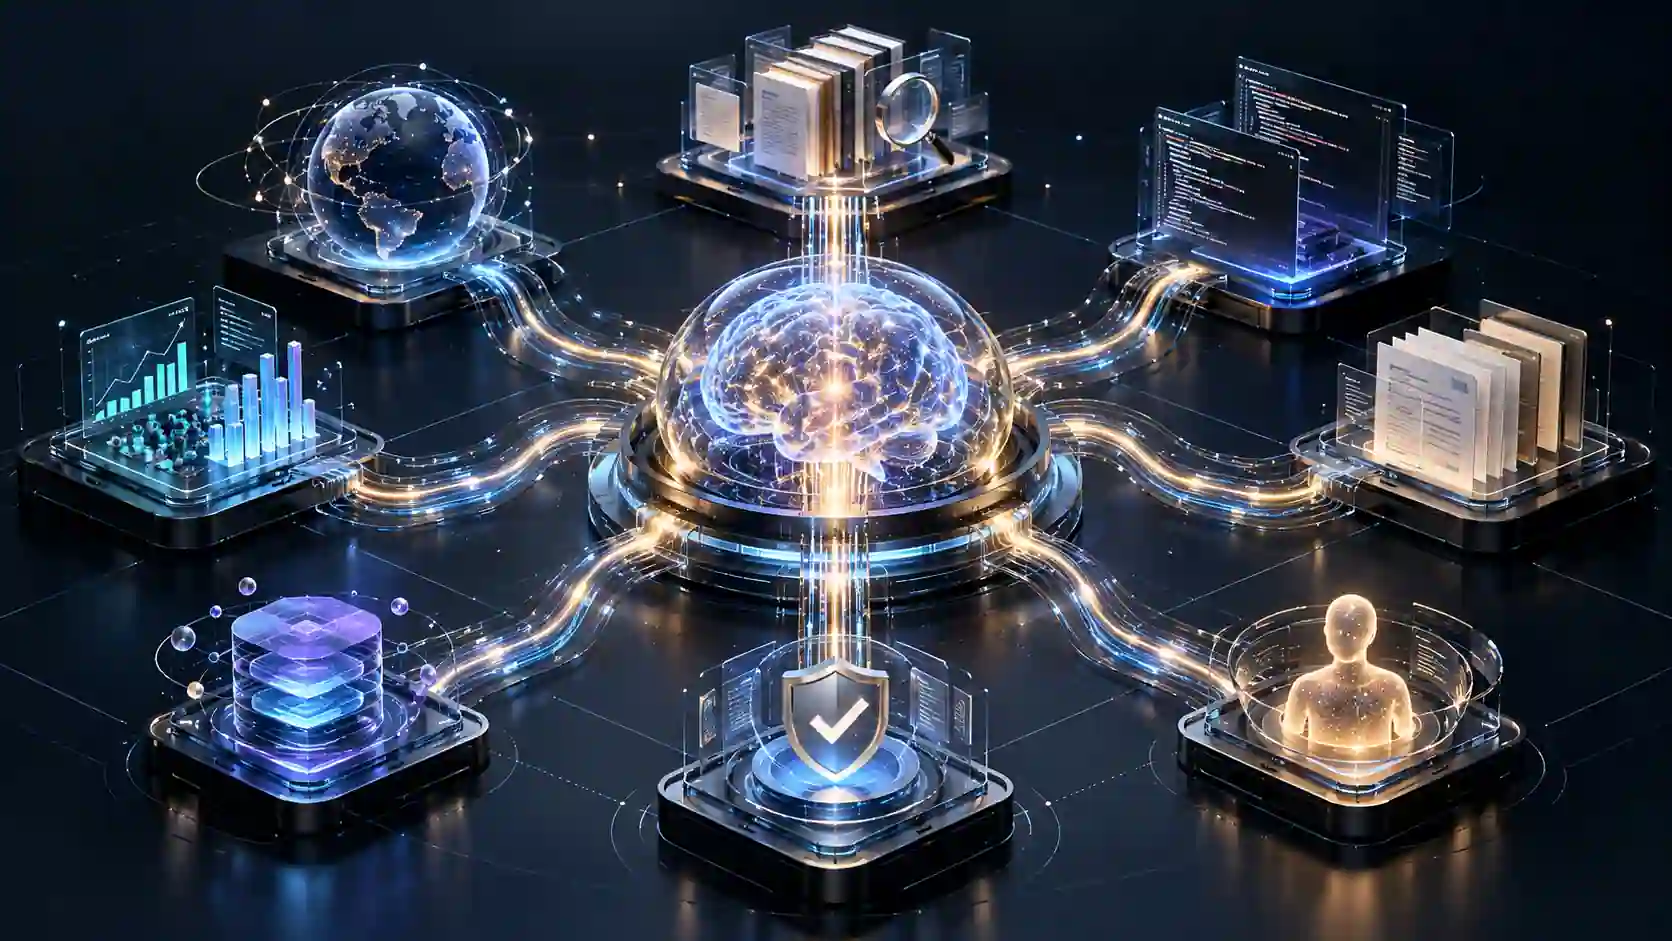
A useful architecture separates control from execution. The orchestrator owns the job. Specialists own bounded subtasks. Tools own side effects. A verifier owns skepticism. Memory and policy sit beside the workflow rather than being hidden inside an ever-growing transcript.
User intent, constraints, required output and success criteria.
Plans, routes, delegates, tracks progress and decides when to stop.
Narrow agents for research, code, data, documents or verification.
Search, APIs, files, databases, code, browsers and MCP servers.
Permissions, approvals, evals, traces, budgets and rollback paths.
The control loop
Turn the request into a goal, constraints and completion criteria.
Choose direct execution, delegation, sequence and parallel branches.
Call specialists and tools with scoped context and permissions.
Read real outputs, errors, state changes and evidence.
Check whether the result satisfies requirements rather than assuming success.
Do not collapse these responsibilities into one giant prompt. The architecture becomes much easier to reason about when state transitions are explicit: planned → running → blocked → needs approval → verifying → complete.
STEP 03 / ORCHESTRATOR
Design the orchestrator as a manager, not as the worker who does everything.
The orchestrator should understand enough about the domain to choose the next action, but its main job is coordination. If it also performs every search, reads every document, writes every line of code and checks its own result, you have created a single overloaded agent with a complicated prompt—not a clean multi-agent system.
A good orchestrator owns six decisions
Who should do this?
Choose a specialist, a deterministic tool or a direct answer.
What does that worker need?
Send the minimum sufficient state, evidence and constraints.
What depends on what?
Sequence dependent work and parallelize independent branches.
What if it fails?
Retry, switch tool, narrow the task, escalate or stop.
Is this good enough?
Invoke validation or a verifier when acceptance criteria are not yet met.
Are we actually done?
End the loop when the outcome—not merely the last agent call—is complete.
Keep the orchestrator's state structured. At minimum track: the original goal, requirements, current plan, completed tasks, evidence, unresolved issues, cost or time budget, approval state and final completion criteria. This state is more reliable than asking the model to reconstruct the entire job from conversation history every time.
STEP 04 / DELEGATION
Handoffs vs agents-as-tools: decide who owns the answer.
OpenAI's current orchestration guidance describes two useful patterns. With a handoff, control moves to a specialist for that branch. With agents as tools, a manager remains in control and calls specialist agents as bounded capabilities. That distinction is more important than framework syntax because it defines ownership.
| Pattern | Who owns the user-facing result? | Best when | Main risk |
|---|---|---|---|
| Handoff | Specialist | A domain agent should take over a branch deeply and interact directly. | Context and policy can drift as ownership moves. |
| Agents as tools | Manager / orchestrator | Specialists provide bounded expertise while one controller owns synthesis. | The manager can become a bottleneck or context sink. |
| Hybrid | Depends on branch | Some work needs direct specialist ownership while other work should stay hidden behind the manager. | More state and routing complexity. |
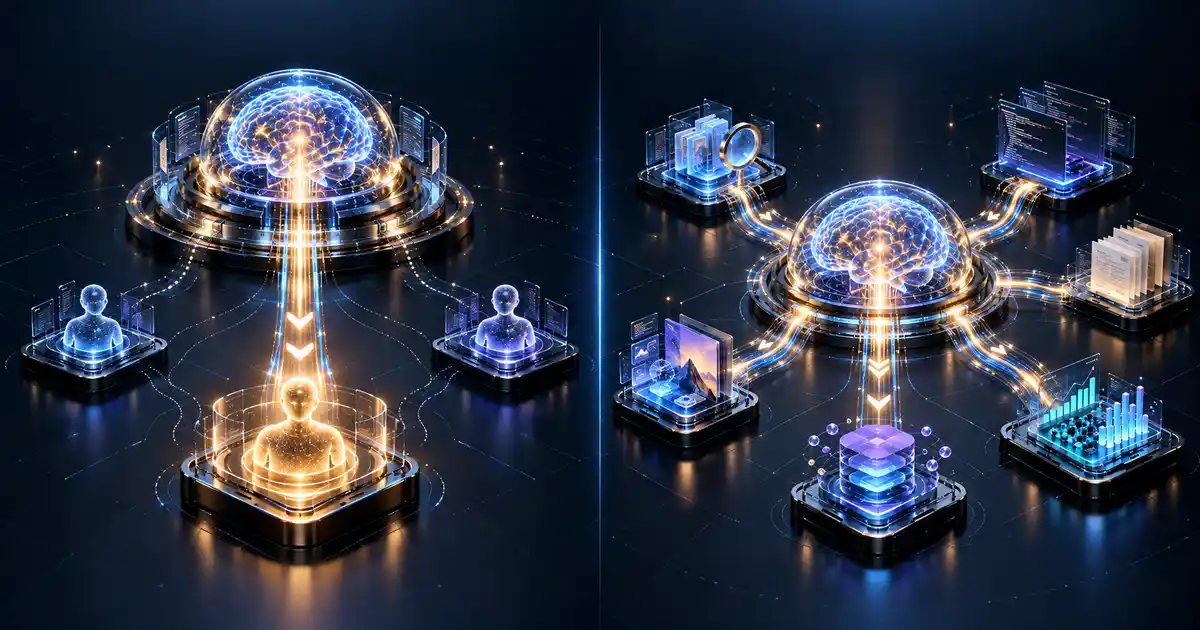
For a research-and-report system, the manager pattern is often easier to govern because one orchestrator can require every specialist to return structured evidence. For customer support or domain-specific conversational branches, a handoff may be cleaner because the specialist needs to own several turns.
STEP 05 / SPECIALIZATION
Make specialists narrow enough to evaluate.
A specialist is useful when it has a meaningfully different job, context, tool set, permission set or model. “Research Agent 1” and “Research Agent 2” with identical capabilities are not specialization; they are duplication unless you deliberately want independent exploration or voting.
Evidence specialist
Finds sources, separates primary from secondary evidence, extracts dates and returns claims with provenance.
Structured analysis specialist
Runs calculations, SQL or code; returns normalized fields and machine-checkable results.
Action specialist
Operates approved apps, APIs, files or a browser inside a tightly scoped permission boundary.
Independent checker
Tests whether evidence, output format and acceptance criteria actually match the requested outcome.
Give each specialist an explicit contract: purpose, allowed inputs, allowed tools, output schema, failure behavior and conditions for escalation. OpenAI's current agent-definition guidance similarly recommends configuring intrinsic specialist decisions—name, instructions, model, tools, handoffs and structured outputs—at the agent level before scaling the workflow.
Do not send the full global transcript to every specialist by default. Give each agent the smallest context package that lets it do its job correctly. Smaller context makes behavior easier to inspect and reduces both cost and accidental leakage.
STEP 06 / TOOLS & MCP
The tool layer is where an agent becomes operational—and where risk becomes real.
Modern agent frameworks treat tools as first-class capabilities: hosted search and file tools, function calls, local execution, computer use, sandboxes, other agents and MCP servers. The architectural question is not “how many tools can the model call?” It is “which capability should be exposed to which agent, under which identity, with what validation?”
Usually lower risk, but retrieved content can still contain malicious or misleading instructions.
Use sandboxes, resource limits and explicit input/output contracts.
Require stricter scopes, idempotency and often human approval.
Treat orchestration capabilities as privileged: they can amplify both good plans and bad plans.
Where MCP fits
Anthropic describes the Model Context Protocol as an open protocol for standardizing how applications provide context and tools to LLM systems. In a super-agent architecture, MCP is best understood as an integration boundary, not as the agent itself. A host connects through MCP clients to servers that expose tools, resources and prompts.
MCP becomes especially useful when integrations multiply. Instead of hard-wiring every model or agent to every external system, you can standardize the tool interface. Anthropic's later engineering work on code execution with MCP also highlights progressive disclosure: agents can discover and load only the tool definitions they need rather than stuffing every tool schema into the context up front.
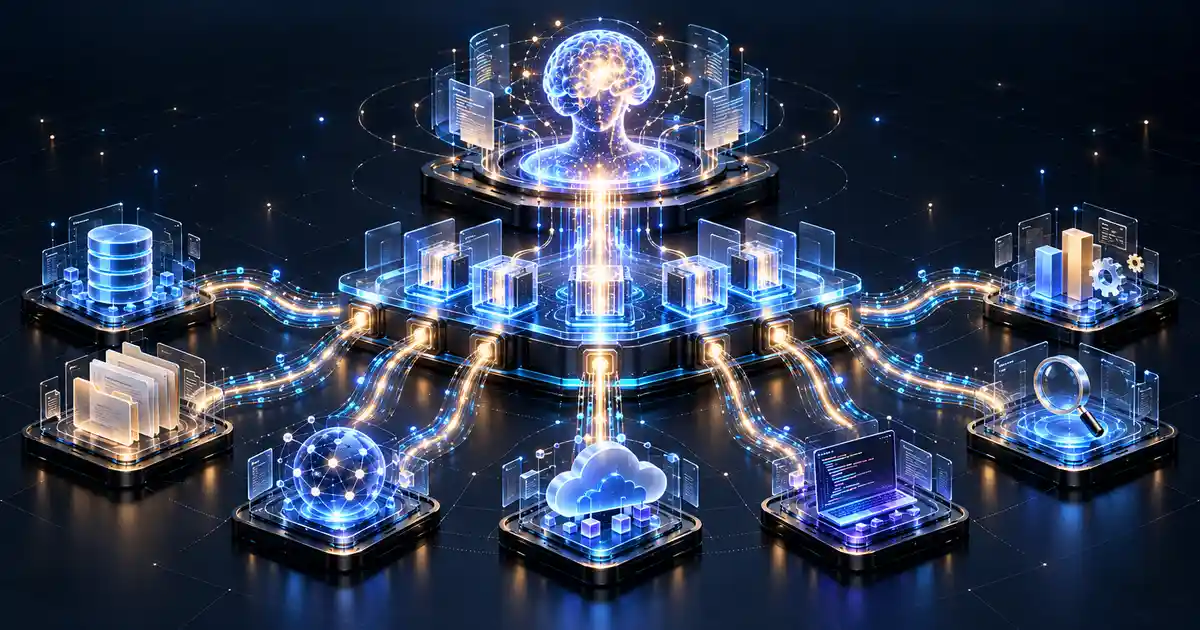
Do not use MCP just because it is popular. If your application has two stable functions, plain function tools may be simpler. Standardization earns its complexity when connectors need to be reusable, discoverable or governed across several agents and applications.
STEP 07 / MEMORY & STATE
Memory should solve a state problem—not become a transcript landfill.
A long-running agent needs continuity, but “remember everything” is a bad architecture. Separate the state required to finish the current job from durable user or workspace knowledge, and retrieve historical information only when it becomes relevant.
What is happening now?
Plan, active tasks, evidence, unresolved questions, budgets, errors and approval state.
What should survive runs?
Stable preferences, policies, project facts and approved reusable knowledge.
What can be fetched later?
Documents, artifacts, logs and indexed knowledge that should not live in every prompt.
What happened?
Tool calls, agent decisions, timings, cost, approvals and state changes for debugging and review.
Store authoritative state outside the model whenever possible. Let the model reason over a concise view of that state. This prevents a subtle class of bugs where the transcript says one thing while the real external system says another.
Use caching for repeated context, not as a substitute for memory
OpenAI's current prompt-caching guidance shows why stable prompt prefixes matter for agent economics: reused context can reduce input cost and latency on supported models. But prompt caching and application memory are different. A cache reuses model-processing work; your application state must still be explicit, durable and auditable.
STEP 08 / PARALLEL WORK
Parallelize independent questions, not dependencies.
Parallel agents are powerful when a task has genuine breadth. Researching five independent markets, inspecting several repositories, or asking separate agents to explore different hypotheses can save wall-clock time and reduce path dependence. Parallelism is much less useful when every step depends on the output of the previous one.
| Work shape | Pattern | Why |
|---|---|---|
| Independent searches | Parallel workers | Each branch can gather evidence without waiting for another branch. |
| Draft → check → revise | Sequential evaluator loop | The evaluator needs the draft before it can produce useful feedback. |
| Unknown subtasks | Orchestrator-workers | The manager discovers and assigns work dynamically. |
| Fixed business process | Deterministic workflow | Model-driven orchestration adds little value when the dependency graph is already known. |
Set concurrency limits. A super agent that can spawn arbitrary workers can also multiply cost, hit rate limits or create cascading tool failures. Give the orchestrator a maximum number of parallel branches and a budget for additional delegation.
STEP 09 / VERIFICATION
Do not let the agent grade success by whether the last call returned 200 OK.
Reliable agent systems separate execution success from task success. A browser action can succeed while booking the wrong date. A database query can run correctly while answering the wrong question. A research agent can return fluent prose with missing evidence.
Build a verification ladder
Required fields, valid JSON, ranges, dates, IDs and output contracts.
Totals reconcile, permissions match, referenced records exist, required citations are present.
Read back the actual state after an action instead of trusting the tool's success message.
Use an independent evaluator when the criterion requires judgment: completeness, contradiction, relevance or instruction adherence.
Escalate high-impact, ambiguous or policy-sensitive outcomes before execution or publication.
OpenAI's evaluation guidance emphasizes that generative systems are variable and need structured evals. For a super agent, evaluate the whole trajectory, not only the final answer: Was the correct tool chosen? Did the system recover safely? Did it exceed the budget? Did it invent evidence? Did the final external state match the intended state?
Create a test set from real tasks and known failure cases. Every production incident that matters should become a regression case. Over time, your evaluation suite becomes the contract that lets you change models, prompts and orchestration without flying blind.
STEP 10 / GOVERNANCE
Autonomy should expand only inside explicit permission boundaries.
Tool-using agents combine probabilistic decisions with real authority. That changes the security problem. Prompt injection, malicious retrieved content, confused identity, over-broad credentials and cascading agent failures can all turn a reasoning mistake into an action mistake. OWASP's Agentic Security Initiative now treats risks such as goal hijacking, tool misuse, identity and privilege abuse, insecure inter-agent communication, memory poisoning and cascading failures as first-class agentic concerns.
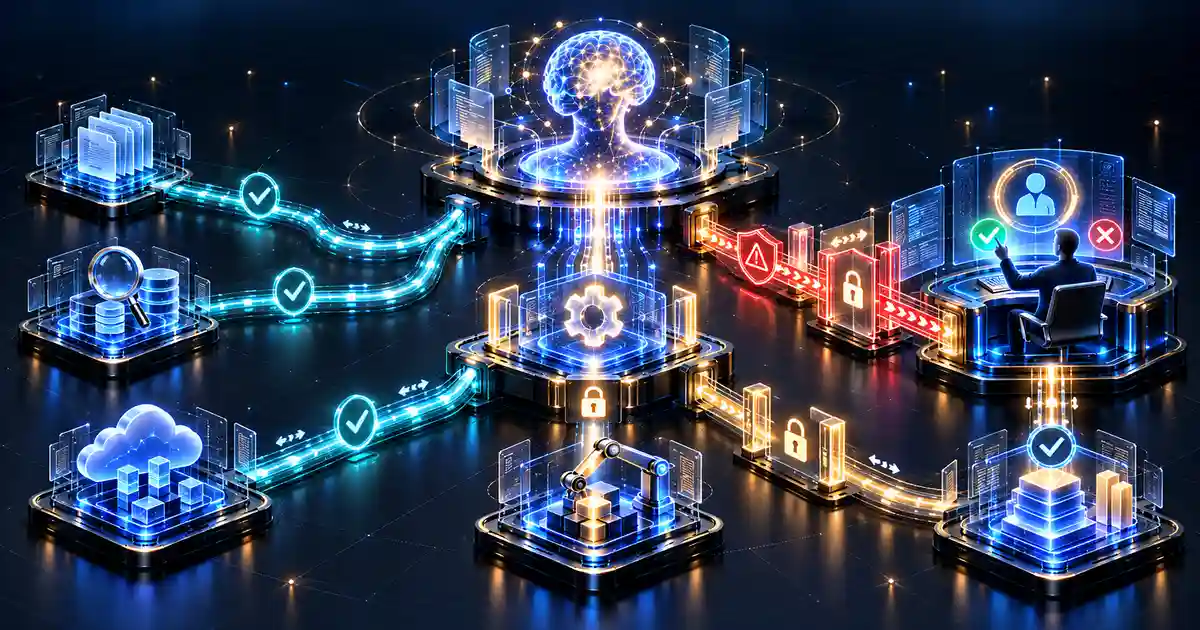
The practical response is architectural: use least privilege, separate identities where appropriate, sandbox execution, validate tool arguments, isolate secrets, require approval for high-impact actions and keep an audit trail. Our AI Agent Security guide covers the security layer in depth.
Least privilege
Each specialist gets only the tools and data it needs for its job.
Typed delegation
Pass structured tasks and expected outputs instead of unrestricted prose whenever possible.
Approval gates
Pause before irreversible, expensive, external or sensitive actions.
Sandboxing
Contain code, files, browser sessions and network access with narrow resource boundaries.
Independent verification
Do not let the same compromised context both propose and approve a high-impact action.
Auditability
Record the task, agent, tool, identity, decision, result and approval path.
STEP 11 / ECONOMICS
Optimize for cost per verified outcome, not tokens per call.
A multi-agent workflow can spend more tokens than a single agent and still be economically better if it completes a valuable task with fewer human corrections. The opposite is also true: a spectacular orchestration graph can burn money on low-value delegation. Measure the full job.
Use expensive intelligence where it changes decisions.
Reserve stronger models for planning, difficult reasoning and synthesis. Use cheaper models or deterministic code for classification, extraction and routine transforms when evals show they are sufficient.
Stop resending the world.
Keep specialist context narrow, retrieve data on demand and use prompt caching for stable reusable prefixes when the provider supports it.
Give spawning a budget.
Cap workers, retries, tool calls and maximum run time. More agents should be a deliberate resource decision.
Parallelize the right work.
Run independent branches concurrently, but keep dependency-heavy work sequential to avoid reconciliation overhead.
Track at least: cost per successful run, median and tail latency, number of model calls, number of tool calls, cache utilization, retry rate, human intervention rate and failure class. SXF's AI Model Cost Calculator can help estimate direct token economics; production agent cost also includes tools, compute, storage and external services.
END-TO-END EXAMPLE
Example: a research-and-report super agent
Assume the goal is: “Research five competitors, verify current pricing and product capabilities from primary sources, identify contradictions, and produce an executive briefing with a comparison table.”
System roles
| Component | Responsibility | Allowed capabilities | Output |
|---|---|---|---|
| Orchestrator | Owns requirements, plan, routing and final completion. | Task state, subagent calls, approval service. | Plan + final briefing. |
| Research agents | One competitor or question per branch. | Web search, source fetch. | Claims + URLs + dates + evidence. |
| Data agent | Normalize pricing and comparable fields. | Code / calculation tools. | Structured comparison rows. |
| Writer | Turn verified facts into a readable briefing. | No write access to source systems. | Draft report. |
| Verifier | Check every material claim against evidence and requirements. | Read evidence + draft. | Pass / issues / missing evidence. |
Execution trace
Five companies, pricing date, required fields, primary-source rule, output format and time budget.
Each branch returns structured evidence rather than prose that another agent must rediscover.
Missing or incomparable values remain explicit instead of being guessed.
The writer cannot invent new facts; it works from the evidence package.
Unsupported claims trigger targeted research, not a full rerun.
Only when required fields pass, uncertainty is disclosed and the deliverable is complete.
This architecture is useful because failures stay local. If one company's pricing cannot be verified, you rerun one research branch. If the writing style is wrong, you rerun the writer. If the verifier flags a contradiction, the orchestrator can request a targeted check instead of starting over.
IMPLEMENTATION BLUEPRINT
Translate the architecture into explicit contracts.
You can implement this pattern with a managed agent runtime, an agents SDK, direct model APIs or a custom orchestration service. Framework choice matters less than preserving the contracts between components.
1. Task envelope
{
  "goal": "Produce a verified competitor briefing",
  "requirements": ["5 companies", "primary sources", "pricing date"],
  "budget": {"max_minutes": 12, "max_worker_runs": 8},
  "risk": {"external_write": false},
  "status": "planned"
}
2. Specialist contract
{
  "role": "pricing_researcher",
  "input": {"company": "...", "as_of": "2026-09-28"},
  "tools": ["web_search", "source_fetch"],
  "output_schema": ["claim", "value", "source_url", "source_date", "confidence"],
  "on_failure": "return_blocker"
}
3. Orchestrator loop
while task is not complete:
  read authoritative task state
  choose next bounded action
  enforce policy and budget
  execute specialist or tool
  record observation
  verify changed state
  escalate when approval or evidence is missing
return only after completion criteria pass
That pseudocode is intentionally provider-neutral. OpenAI's current documentation recommends the Agents API for new managed agent applications, while direct APIs and SDK approaches remain valid when you need more control over the loop or execution environment. The invariant is the same: keep the state, permissions, tools and completion rules explicit.
FAILURE MODES
The hardest bugs appear between agents, tools and state.
Transcript and reality diverge
The agent believes an action succeeded but the external system has a different state. Always read back important changes.
Every specialist sees everything
Large shared context increases cost, distraction and accidental data exposure.
Agents keep handing work around
Set ownership rules, hop limits, budgets and explicit terminal states.
The same context proposes and blesses an action
Use independent checks and human gates for important outcomes.
Too many overlapping capabilities
Remove redundant tools, clarify descriptions and scope availability by role.
The process ended, but the job did not
Verify acceptance criteria and environment state before marking a task complete.
Other failures are economic rather than functional: runaway retries, unnecessary premium-model calls, duplicate searches and sequential work that should have been parallel. Treat cost and latency regressions as reliability bugs because they determine whether the system can remain in production.
PRODUCTION CHECKLIST
Before you call it a super agent, verify the system—not the label.
A human can tell exactly what the system owns and what “done” means.
You have evidence that specialization, parallel work or separate permissions improve the task.
Plans, approvals, evidence and external results can be inspected independently.
Read, write and irreversible actions are intentionally separated.
Schema validation, deterministic checks, evals and human review cover the relevant risk.
Traces include agent calls, tools, state changes, errors, approvals, cost and latency.
Workers, retries, time and model spend cannot grow without limit.
Model or prompt changes are evaluated against recurring production tasks before rollout.
The strongest super agent is not the one with the most agents. It is the smallest architecture that can reliably own the outcome, prove what it did and stop safely when it cannot.
FAQ
Common questions about building AI super agents
What is the difference between an AI agent and an AI super agent?
An AI agent can pursue a multi-step goal and use tools. An AI super agent adds a broader control layer: it can orchestrate specialists, route tools and models, preserve task state, verify work and govern an end-to-end outcome.
Do I need multiple agents to build a super agent?
No. A strong design can begin with one orchestrating agent plus tools. Add specialist agents only when narrower instructions, different permissions, parallel work or different models measurably improve the result.
When should I use MCP in a super agent?
Use MCP when a standardized connection layer makes tool and data integrations easier to reuse or govern. Small systems with only a few functions may not need MCP at all.
What should the orchestrator do?
The orchestrator should interpret the goal, decide whether to answer directly or delegate, select specialists and tools, track task state, evaluate progress, request approvals when needed and decide when the work is complete.
How do you make a super agent reliable?
Use narrow specialist roles, structured state, least-privilege tools, explicit success criteria, deterministic validation where possible, evaluation datasets, traces and a verifier or review stage before important outcomes are accepted.
Are multi-agent systems always better than a single agent?
No. Multi-agent systems add cost, latency and coordination failure modes. They are most useful when the work can be decomposed into genuinely different or parallel tasks.
How do you control the cost of a super agent?
Route simple work to cheaper models, avoid unnecessary agent calls, reuse stable context through caching when supported, parallelize only independent work, cap retries and measure cost per successful outcome rather than cost per prompt.
What actions should require human approval?
High-impact or irreversible actions such as payments, destructive changes, production deployment, external communications, permission changes and sensitive data operations should usually remain behind explicit approval gates.
PRIMARY SOURCES
Research used for this guide
The architecture above is SXF's synthesis. Technical claims and current platform guidance were checked against primary documentation and engineering sources available on September 28, 2026.
RELATED SXF GUIDES